
LLM 101
A clear primer on large language models: their history from n-grams to the Transformer to ChatGPT, how they work (tokens, attention, context windows), the training pipeline (pretraining, SFT, RLHF, alignment), prompting and RAG, the key companies and people, and the numbers and milestones that define the field.
604 cards10 lessonsFree
Already have FlashFeed?Open this pack
Get this pack on your phone
Scan with your phone's camera.
flashfeedlearningapp.com/packs/llm-101
Part of the Learn AI collection.
10 lessons.
Each lesson has a study guide to read and objectives you can test yourself on. Its cards and games show up in your feed. Try one of its cards right here. Play a few of its games here too.
-
 Unsplash · Glen Carrie · Unsplash License ↗01
A Brief History of LLMs
Before the Transformer · The GPT era · ChatGPT and the modern wave
Lesson 1 · 10 cardsUnsplash · Glen Carrie · Unsplash License ↗Pre-Transformer NLP: n-grams
Early language models predicted the next word by counting how often word sequences appeared in text (n-grams). They were fast but couldn't capture meaning across long distances — only the last few words mattered.
 Pexels · Magda Ehlers ↗
RNNs and LSTMs
Recurrent Neural Networks (RNNs) and their improved variant, Long Short-Term Memory (LSTM) networks, processed text sequentially, keeping a hidden 'memory' of earlier words. They dominated NLP from roughly 2014–2017 but struggled with long sequences due to vanishing gradients.
 FlashFeed original diagram · CC-BY-4.0
word2vec (2013)
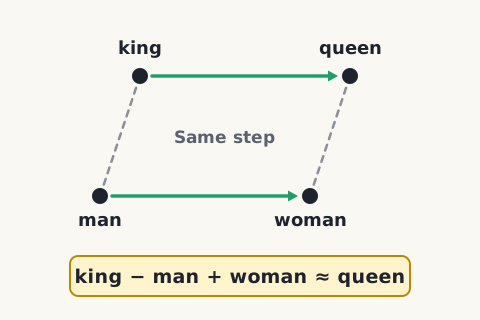
Mikolov and colleagues introduced word2vec, which learned dense vector representations of words from large text. It famously showed that vector arithmetic captured meaning (king − man + woman ≈ queen), making it a foundational embedding technique for all later NLP.
 FlashFeed original diagram · CC-BY-4.0
seq2seq and attention (2014–2015)
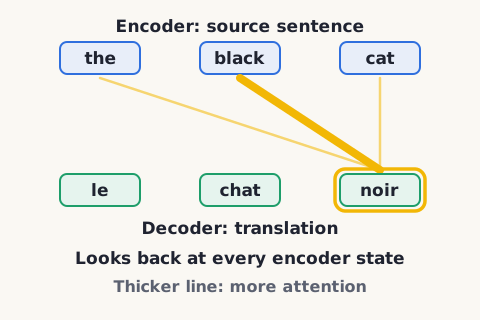
Sutskever's sequence-to-sequence model used an encoder–decoder LSTM to translate sentences. Bahdanau then added an attention mechanism that let the decoder 'look back' at all encoder states, sharply improving translation — and previewing the self-attention at the heart of the Transformer.
 AI-generated (gpt-image-1.5)
Attention replaces recurrence
The 2017 Transformer paper by Vaswani et al. proved that recurrence could be discarded entirely — a model built from attention alone was enough.
 Pexels · Matheus Bertelli ↗
BERT (2018): bidirectional pretraining
Devlin and colleagues at Google introduced BERT in a paper in October 2018. Unlike left-to-right models, BERT was pretrained to predict masked words using context from both sides of a sentence, setting new state-of-the-art results on eleven NLP benchmarks.
 Pexels · Steve A Johnson ↗
GPT-1 (2018): the first GPT
OpenAI released GPT-1 in 2018 with 117 million parameters, trained on BooksCorpus. It showed that a generative pretrained Transformer, fine-tuned on downstream tasks, could match task-specific models — validating the pretraining paradigm that everything since has built on.
 AI-generated (gpt-image-1.5)
GPT-2 (2019): scaling surprises
GPT-2 scaled to 1.5 billion parameters, trained on 40 GB of web text. Its fluent, coherent generation was striking enough that OpenAI initially withheld the full model over misuse concerns — an early signal of the field's growing awareness of capability risks.
 Pexels · panumas nikhomkhai ↗
GPT-3 (2020): the few-shot giant
OpenAI released GPT-3 in 2020 with 175 billion parameters — over 10× larger than any prior dense model. Its key finding: given only a few examples in the prompt ('few-shot'), it could perform tasks it was never explicitly trained on, demonstrating in-context learning at scale.
 AI-generated (gpt-image-1.5)
Kaplan's scaling laws
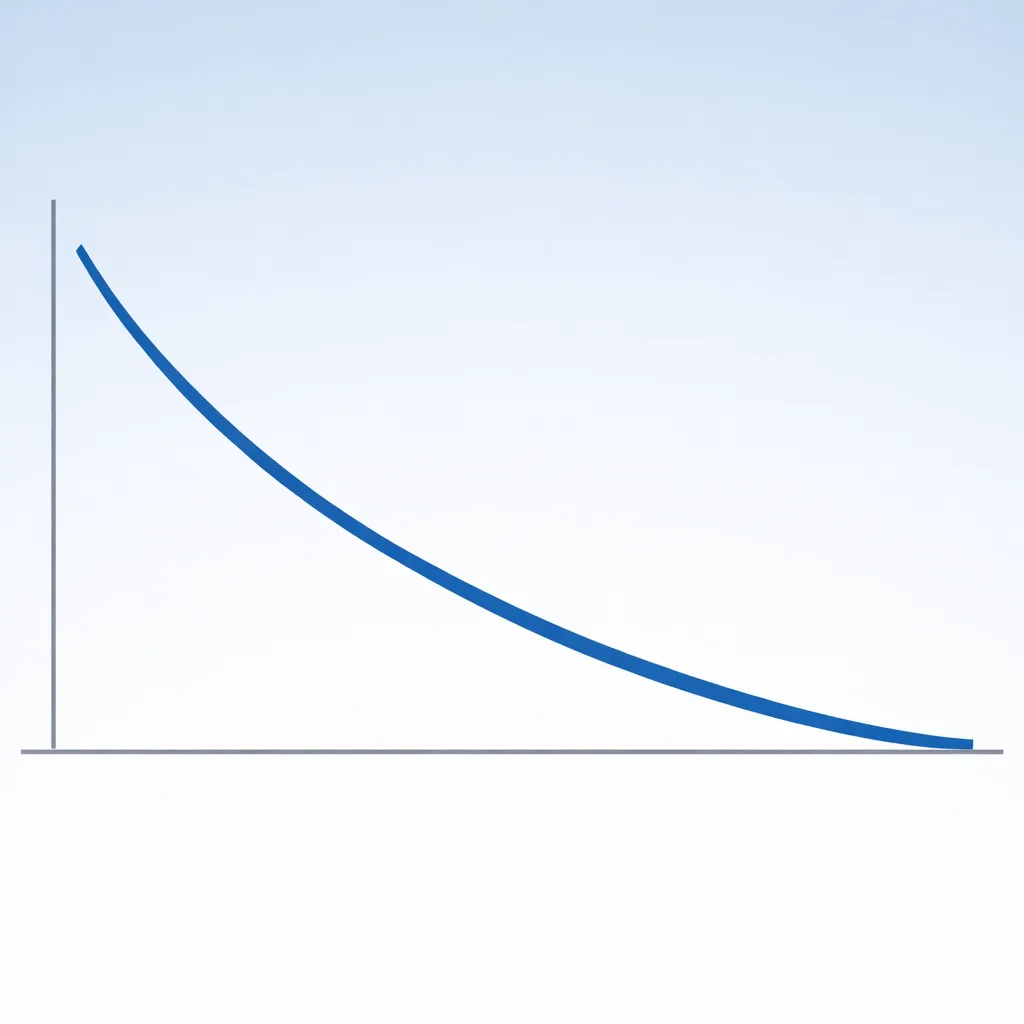
Kaplan et al.'s 2020 scaling laws showed that loss falls predictably as a power function of compute, data, and parameters — a quantitative map that justified ever-larger models.
1 / 10What did the Chinchilla (2022) result revise about GPT-3?
Chinchilla showed GPT-3 was undertrained given its 175B parameters: the 70B-parameter Chinchilla, trained on about four times as much data as the 280B Gopher at the same compute budget, outperformed both Gopher and GPT-3. Chinchilla revised the power laws rather than rejecting them.
Lesson 1 has 58 cards. Keep going in the free app.
Question -
 FlashFeed original diagram · CC-BY-4.002
How LLMs Work
Tokens, embeddings and attention · How text is generated
Lesson 2 · 5 cardsFlashFeed original diagram · CC-BY-4.0Why hallucinations happen
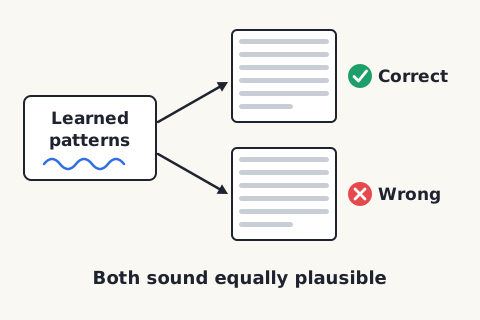
LLMs are trained to produce plausible text, not to retrieve verified facts. With no internal fact-checker, they interpolate from patterns in their training data — so they 'fill in' convincing but wrong details the same way they fill in correct ones. Grounding techniques like RAG are the main mitigation.
 FlashFeed original diagram · CC-BY-4.0
Next-token prediction
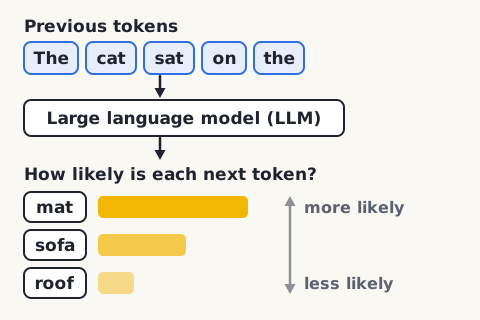
The core skill an LLM learns in training is next-token prediction: given all previous tokens, estimate how likely each possible next token is. Its broader language ability follows from that one skill.
 FlashFeed original diagram · CC-BY-4.0
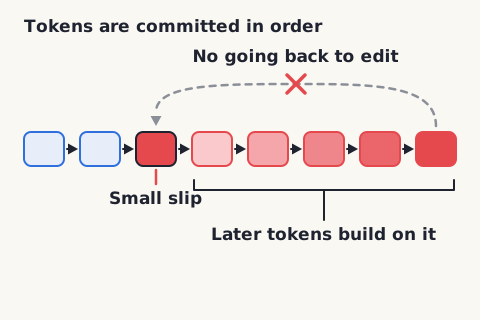
Why early errors compound
A model can't go back and edit its own output — it commits to each token in sequence, so a small factual slip early in an answer compounds as later tokens build on the mistake.
 AI-generated (gpt-image-1.5)
What logits are
Logits are the raw, unnormalized scores an LLM assigns to every possible next token, before those scores are converted into probabilities.
 FlashFeed original diagram · CC-BY-4.0
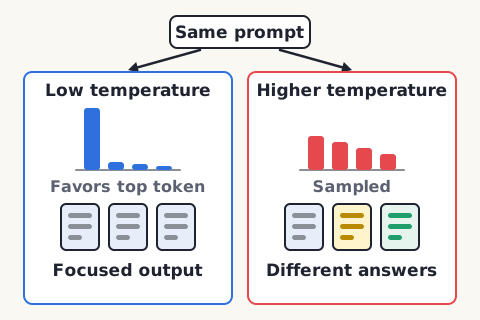
Low temperature, focused output
Setting an LLM's temperature low makes it favor the safe, high-probability token, producing output that is focused and as deterministic as possible.
1 / 5On average, roughly how much of a word does a single token represent?
A token is the basic unit an LLM processes — in English, on average about three-quarters of a word. Common words like 'the' are one token, while rarer strings like 'ChatGPT' split into several pieces. Tokens (not words) are what context limits, pricing, and speed are measured in.
Lesson 2 has 64 cards. Keep going in the free app.
Question -
 AI-generated (gpt-image-1.5)03
The Training Pipeline
Pretraining to RLHF · Alignment, inference and compute
Lesson 3 · 5 cardsAI-generated (gpt-image-1.5)Constitutional AI's self-critique
In Anthropic's Constitutional AI, the model critiques and revises its own outputs against a written set of principles, then trains on those AI-generated preferences — reducing reliance on human harm-labeling.
 FlashFeed original diagram · CC-BY-4.0
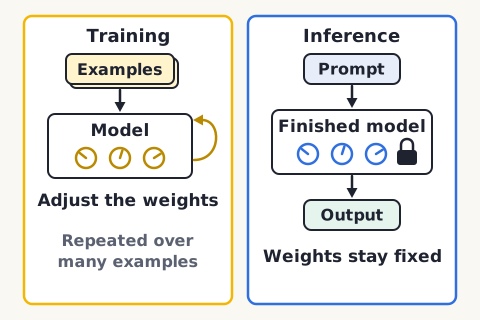
Training vs. inference — the key distinction
TRAINING updates a model's weights with gradient descent over billions of examples — done once or rarely, on massive GPU clusters over weeks or months. INFERENCE runs the finished, frozen model on a prompt — cheap per call, done billions of times a day. This is why training a large model is costly but querying an API is cheap.
 FlashFeed original diagram · CC-BY-4.0
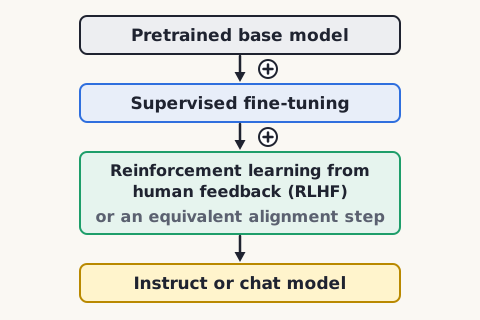
Base model plus alignment
An instruct or chat model is produced by taking a pretrained base model and adding supervised fine-tuning plus RLHF, or an equivalent alignment step.
 Pexels · panumas nikhomkhai ↗
Why training a large model costs millions
Training a large model is expensive because it runs on massive GPU clusters for weeks or months at a cost of millions, while querying an API afterward is cheap per call.
1 / 5Which is NOT true of the base model produced by pretraining?
Pretraining yields broad world knowledge and text prediction, but explicitly does NOT teach instruction-following or helpfulness — that requires SFT and RLHF. Base models are raw material, not safe for general users.
Lesson 3 has 54 cards. Keep going in the free app.
Question -
 Pexels · Diana ✨ ↗04
Prompting, RAG and Using LLMs
Prompting techniques · RAG, tools and agents
Lesson 4 · 5 cardsPexels · Diana ✨ ↗Prompting vs. RAG vs. fine-tuning
PROMPTING: best for general tasks, formatting, persona, and zero/few-shot — no training data or training cost, but limited by context size. RAG: best when you need fresh or proprietary knowledge without touching weights, ideal for document Q&A. FINE-TUNING: best for persistent style, behavior, or domain adaptation baked into the model — expensive and data-hungry, but it persists across every call.
 FlashFeed original diagram · CC-BY-4.0
Vector databases, explained
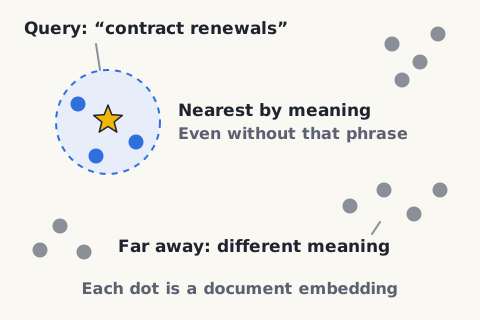
A vector database stores document embeddings and finds relevant material through fast similarity search — matching by meaning, not exact keyword matching.
 FlashFeed original diagram · CC-BY-4.0
Why RAG chunks documents
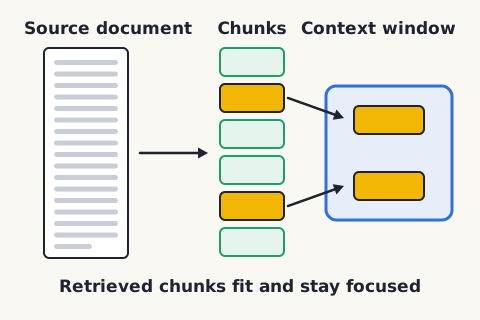
Source documents are split into smaller segments before being embedded for RAG so the retrieved passages fit the context window and stay semantically focused.
 FlashFeed original diagram · CC-BY-4.0
The agent planning loop
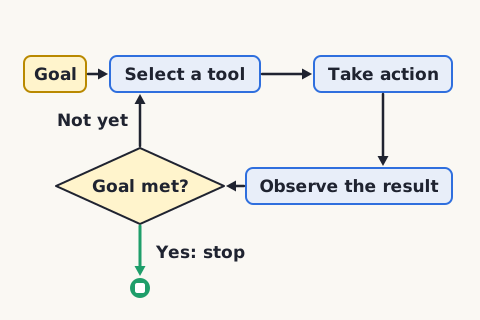
An LLM agent differs from a single-prompt interaction by running a planning loop: it acts as a controller that selects tools, takes action, and observes results until the goal is met.
 Pexels · Daniil Komov · Pexels License ↗
What function calling produces
In function calling, the model itself produces a structured, well-formed call — it's the host application that actually runs that call against the real API or tool.
1 / 5What is the key limitation of prompting alone?
Prompting costs nothing but is bounded by context and the model's existing weights, so it can't supply knowledge the model never learned. That gap is exactly why RAG, function calling, and agents exist.
Lesson 4 has 60 cards. Keep going in the free app.
Question -
05
Companies, People and Models
The companies · The godfathers and key researchers · Founders, leaders and the ecosystem
Lesson 5 · a questionWhich model family is made by xAI, the lab Elon Musk founded in 2023?
xAI makes Grok, which is integrated with X. Claude is Anthropic's, Llama is Meta AI's, and Gemini is Google DeepMind's.
Lesson 5 has 61 cards. Keep going in the free app.
- Take the lessons with you. Free, no account.Download on the App Store ↗Get it on Google Play ↗
-
06
Key Numbers and Milestones
Model sizes and dates · Scaling, context and misconceptions
Lesson 6 · a questionWhich sequence correctly orders these milestones in time?
The spine of the modern timeline: GPT-3 in 2020, ChatGPT on Nov 30, 2022, and GPT-4 on March 14, 2023 — the under-three-year stretch in which LLMs went from research artifact to mass technology.
Lesson 6 has 59 cards. Keep going in the free app.
-
 Pexels · cottonbro studio · Pexels License ↗07
What LLMs Are Good For
Language and writing tasks · Knowledge, search and code · Work and everyday tasks · High-stakes domains and choosing well
Lesson 7 · 10 cardsPexels · cottonbro studio · Pexels License ↗Code generation: the copilot pattern
Code-trained LLMs suggest lines, whole functions, and boilerplate from a comment or docstring. In one controlled experiment (Peng et al., 2023), developers asked to implement an HTTP server in JavaScript finished 55.8% faster with GitHub Copilot, and less experienced developers benefited most. The value is a useful starting point, not guaranteed correctness — review still matters.
 FlashFeed original diagram · CC-BY-4.0
Document Q&A over your own files
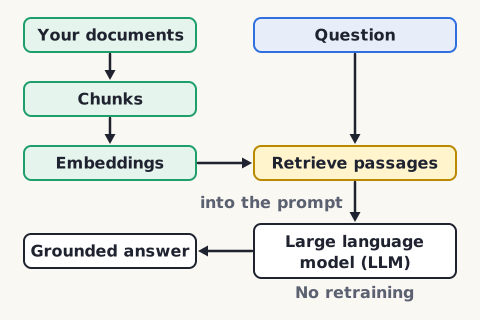
Chunk private documents, embed them, and retrieve relevant passages into the prompt (RAG) to get an assistant grounded in your own data — manuals, contracts, wikis — without retraining. It is a widely used enterprise LLM pattern because it is usually cheaper than retraining, the knowledge base is updatable, and proprietary data stays out of model weights.
 Pexels · panumas nikhomkhai ↗
RAG Is Often Preferred to Fine-Tuning
RAG often grounds an LLM in private company knowledge more cheaply than fine-tuning, lets the knowledge base update without retraining, and keeps proprietary data out of the model's weights.
 FlashFeed original diagram · CC-BY-4.0
Embeddings Search By Meaning
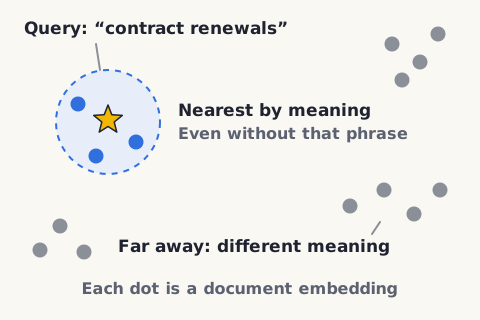
Semantic search retrieves passages by meaning using embeddings, so a query like "contract renewals" can surface documents that never use that phrase — though it weakens on niche jargon the embedding model doesn't cover.
 AI-generated (gpt-image-1.5)
Healthcare: assist, don't diagnose
LLMs can summarize clinical notes, draft discharge summaries, and surface literature. But medical hallucinations — a wrong dosage, a misattributed contraindication — can harm patients, and research suggests hallucination may be intrinsic to LLMs. Deployment requires clinician review of every output and domain-specific evaluation.
 Pexels · kaboompics.com · Pexels License ↗
Legal: research and drafting, never final
LLMs are strong at contract summarization, clause extraction, and statute research. But in 2023, two attorneys were sanctioned after ChatGPT fabricated case citations they filed in federal court — a canonical cost of unsupervised use. All LLM legal content must be cite-verified by a qualified attorney.
 Pexels · RDNE Stock project · Pexels License ↗
Finance: analysis aid, regulated output
LLMs help with earnings summaries, filing sentiment, and data extraction. In regulated finance, outputs that drive investment, lending, or compliance carry regulatory exposure, and hallucinated figures can cause real harm. Best practice: RAG over verified data plus mandatory human review before any customer-facing output.
 AI-generated (gpt-image-1.5)
Human-in-the-loop: when and why
Let the cost of verification set the level of autonomy. If checking the output is fast and cheap — reading a draft, running a test — more automation is fine. If verification is expensive, or an error would be costly and hard to undo — surgery, a legal filing, a trade — keep a human checkpoint before every consequential action.
 Pexels · Donald Tong · Pexels License ↗
The Copilot Pattern
In the copilot pattern, the LLM suggests, drafts, or assists, but a human must approve before anything takes effect — it accelerates work without ever finalizing it on its own.
1 / 10Which of these is NOT listed among the language and writing tasks LLMs handle well?
Simplification, rewriting/tone-shifting, and classification are all listed language strengths. Needing exact arithmetic without tools is named as a marker of poor LLM fit.
Lesson 7 has 87 cards. Keep going in the free app.
Question -
 AI-generated (gpt-image-1.5)08
Limits and Responsible Use
Reliability and staleness · Bias, privacy and your data · Security and societal risks · Limits, safeguards and deployment
Lesson 8 · 10 cardsAI-generated (gpt-image-1.5)Why hallucinations cost you
A hallucinated output ranges from embarrassing (a wrong product name) to costly (fabricated legal citations filed in court, which drew sanctions in a documented 2023 case) to dangerous (a plausible but wrong drug dosage). The damage scales with how hard the claim is to verify and how much the user trusts the model's fluent, confident tone.
 Pexels · Google DeepMind ↗
Mitigating hallucination: the toolkit
Four complementary defenses: ground answers in retrieved sources (RAG); require the model to quote and link citations; prompt or fine-tune it to say 'I don't know' rather than confabulate; and for high-stakes output, have a domain expert verify before use. No single measure is enough on its own — they layer.
 Pexels · Yusuf Kayode · Pexels License ↗
Confident tone is not correctness
LLMs usually write authoritative-sounding prose whether or not they have reliable information, so fluency is a poor signal of accuracy. A low-probability guess and a well-established fact can be written in much the same register, and the surface text does not reliably show which is which.
 FlashFeed original diagram · CC-BY-4.0
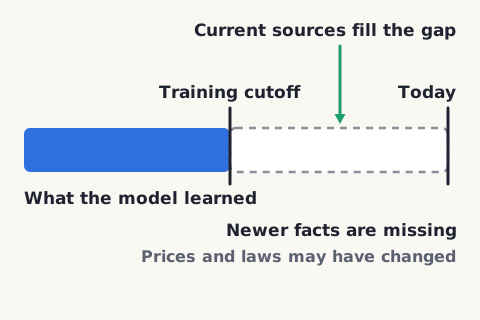
The staleness gap
A model is often deployed months or years after its training cutoff, and will confidently discuss outdated facts — prices, laws, office-holders, software versions — as if they were current. Use RAG with live data for time-sensitive tasks, or at least tell users the model's cutoff.
 Pexels · Nataliya Vaitkevich · Pexels License ↗
Hallucination Isn't A Glitch
LLMs hallucinate because they're trained to predict plausible-sounding text, not to verify it — there's no built-in mechanism checking whether an output is actually factually grounded before it's produced.
 Openverse · ccPixs.com · CC BY 2.0 ↗
Where bias comes from
LLMs learn from human-written text that over-represents certain languages, demographics, and viewpoints — a model trained mostly on English-language Western web content reflects those perspectives by default. Bias enters at data collection, pretraining, and fine-tuning, and is partly mitigated but rarely eliminated at each stage.
 Pexels · Tima Miroshnichenko · Pexels License ↗
How bias shows up
The documented forms are systematic, not random: stereotypical associations (job titles tied to genders), accuracy gaps (worse on African-American Vernacular English than Standard American English), cultural skew (assuming Western norms in advice), and weaker output in low-resource languages. The same groups are disadvantaged repeatedly.
 Pexels · Nicolas Foster ↗
Why bias is hard to remove
Alignment and filters can curb the most obvious bias, but can't re-balance the underlying training distribution — and debiasing one dimension can introduce disparities elsewhere. Evaluating fairness across thousands of groups and tasks is intractable to cover fully; the NIST AI RMF names systemic, computational/statistical, and human-cognitive biases as categories that must be managed continuously.
 homegets.com (Openverse) · by 2.0 ↗
What happens to data you paste
On a consumer LLM product, your inputs may be logged for abuse monitoring, used to train future models, or seen by support staff. Enterprise API tiers with data-processing agreements typically forbid training on your data. Never paste credentials, patient data, or confidential IP into a consumer chat, and read the provider's data-use terms before pasting anything sensitive; regulated data such as patient records belongs only in a product covered by an appropriate business agreement.
 Pexels · Anna Shvets ↗
Training-data memorization and PII
LLMs can memorize and regurgitate fragments of their training data — email addresses, phone numbers, whole passages — when prompted the right way. Research shows multi-query extraction attacks pull out far more PII than simple probes, and fine-tuned models leak more than base models, especially when trained on repeated sensitive data.
1 / 10At which three stages does bias enter an LLM?
Bias enters at data collection, pretraining, and fine-tuning — three distinct stages, each partly mitigated but rarely eliminated. Tokenization and decoding are mechanics, not bias-entry stages.
Lesson 8 has 68 cards. Keep going in the free app.
Question -
09
Quick Recall
Core terms
Lesson 9 · a questionA token is the unit an LLM actually processes. Roughly how much text does one token represent?
A token averages about ¾ of a word — it is the unit models process and the currency of context limits and pricing. Tokens are usually sub-word pieces, so "exactly one word" is wrong.
Lesson 9 has 45 cards. Keep going in the free app.
-
10
Key Concepts
Key People · Key Things
Lesson 10 · a questionWhich researcher is NOT one of the three who shared the 2018 Turing Award for deep learning?
The 2018 Turing Award went jointly to Bengio, Hinton, and LeCun. Andrew Ng is influential in AI as a Google Brain co-founder and educator, but he was not among the three recipients.
Lesson 10 has 48 cards. Keep going in the free app.
What you'll be able to do 47 objectives, from the pack's lessons
- Trace the pre-Transformer progression from RNNs/LSTMs through the attention mechanism to the 2017 Transformer.
- Contrast the Kaplan (2020) and Chinchilla (2022) scaling laws and what each revised about optimal model training.
- Explain how BERT's bidirectional (masked) pretraining differed from GPT and identify the GPT-1 to GPT-3 progression.
- Describe how RLHF/InstructGPT and the ChatGPT and GPT-4 launches turned capable models into useful products.
- Recognize the modern open-weight wave (LLaMA, Mistral) and the frontier assistants (Claude, Gemini, GPT-4).
- Explain how text becomes tokens and then embedding vectors a model can compute over.
- Describe the Transformer, self-attention, context window, and parameters that make up a model's internals.
- Describe next-token prediction and autoregressive generation as the core loop that produces text.
- Explain how logits and the temperature knob shape which next token is sampled.
- Explain why LLMs hallucinate and recognize emergent abilities that appear only at scale.
- Explain self-supervised pretraining and why the resulting base model is not yet a helpful assistant.
- Describe supervised fine-tuning as training on prompt/response pairs to make a model follow instructions.
- Explain how RLHF and its reward model align a model, and how RLAIF and Constitutional AI scale that alignment.
- Identify the instruct/chat model as the aligned product of the full base-plus-SFT-plus-RLHF pipeline.
- Distinguish training from inference and relate the FLOPs compute cost to why training a large model is costly but querying it is cheap.
- Describe what a prompt and a system prompt contain, and why prompting, though free, can't give a model knowledge it wasn't trained on.
- Distinguish zero-shot, few-shot and chain-of-thought prompting, explain in-context learning, and recognize step-by-step reasoning as emergent.
- Explain RAG and its supporting components — vector databases and chunking — for grounding a model in external knowledge.
- Describe function calling and LLM agents, and how an agent's planning loop differs from a single-prompt interaction.
- Contrast fine-tuning with RAG as ways to add knowledge or behavior, one baking into weights and the other into context.
- Match the US frontier labs (OpenAI, Anthropic, Meta, xAI) to their flagship model families.
- Identify the international and second-tier labs (Google DeepMind, Mistral, Cohere) and the lab that drove open-source LLMs.
- Recognize the three 'godfathers of deep learning' who shared the 2018 Turing Award.
- Identify pivotal LLM researchers — Vaswani, Sutskever, and Karpathy — and their contributions.
- Match today's lab leaders (Altman, the Amodeis, Hassabis) and the infrastructure players (Nvidia, Hugging Face).
- Recall the parameter counts of the GPT line (GPT-1, GPT-2, GPT-3) and GPT-3's training-data size.
- Recall the parameter counts of other landmark models (BERT-large, LLaMA's 7B-to-65B family, Mistral 7B and PaLM) and compare them with GPT-3.
- Place the key release years in order: BERT, GPT-2, GPT-3, LLaMA, ChatGPT, and GPT-4.
- Recall the ChatGPT and GPT-4 launch years and ChatGPT's record two-month climb to 100 million users.
- Recall the scaling-law figures (Kaplan year, Chinchilla's ~20 tokens/parameter) and context-window growth, and why bigger isn't always better.
- Identify LLM strengths across language tasks — summarization, translation, rewriting, editing, classification, and simplification.
- Explain LLM knowledge/search use cases (research, semantic search, extraction, RAG) and coding assistance (Copilot speedup, explanation, debugging, tests).
- Identify everyday work and personal tasks LLMs assist — support, drafting, meeting notes, data cleaning, tutoring, brainstorming — with their catches.
- Apply the copilot pattern and the cost-of-verification framework to decide how much automation a task warrants.
- Judge good vs poor LLM fit and the human-review guardrails required in healthcare, legal, and finance.
- Explain why LLMs hallucinate and what a knowledge cutoff means for stale, confidently-stated answers.
- Identify where LLM bias enters (data collection, pretraining, fine-tuning) and how it shows up, such as the AAVE accuracy gap.
- Describe what can happen to data pasted into a consumer LLM and the memorization/PII-extraction risk.
- Explain prompt injection and jailbreaks, automation bias, and why tool-enabled agents widen the attack surface.
- Recognize red-teaming and model cards, explain how non-determinism limits reproducibility, and why filters alone don't make a model safe for high stakes.
- Recall the core architecture terms — Transformer, token, self-attention, and context window — instantly.
- Recall the training terms — pretraining, RLHF, and Chinchilla's ~20-tokens-per-parameter rule.
- Recall the usage terms — RAG, inference, hallucination, few-shot, and emergence.
- Recognize the three Turing-Award 'godfathers of deep learning' — Bengio, Hinton, and LeCun.
- Identify key researchers behind modern LLMs — Sutskever and Radford at OpenAI, and educator Andrew Ng.
- Recognize foundational techniques and architectures — word2vec, LSTM, and the Transformer.
- Recognize landmark models — BERT, GPT-3, and ChatGPT — including GPT-3's 175-billion-parameter scale.
Study guide.
The same study guide as in the app, one page for each lesson, with its key facts and a self-test.
Built from 2 sources.
4 of its 606 cards cite a source. These are the sources it cites.
Hover over a photo, or tap its i, to see where it came from. All 6:
- Lesson 1: Unsplash · Glen Carrie · Unsplash License ↗
- Lesson 2: FlashFeed original diagram · CC-BY-4.0
- Lesson 3: AI-generated (gpt-image-1.5)
- Lesson 4: Pexels · Diana ✨ ↗
- Lesson 7: Pexels · cottonbro studio · Pexels License ↗
- Lesson 8: AI-generated (gpt-image-1.5)
- Cards
- 604
- Lessons
- 10
- Version
- 1.1.21
- Language
- English
The whole pack is one file. Read the pack file ↗
FlashFeed is on the App Store and Google Play.
FlashFeed is free on iPhone and Android, and needs no account.